
Google ADK 2.14: Stable sandboxes and A2A – the upgrade trade-offs
Google stabilizes key agent APIs, enhances repeated evaluation and narrows free-form skill commands. Existing deployments must check breaking changes.
Stable APIs aid planning, but A2A authorization, sandbox boundaries and breaking changes still require testing before an upgrade.
1. What became stable
The release names BaseEnvironment, LocalEnvironment, EnvironmentToolset, DaytonaEnvironment and E2BEnvironment as stable. Read-file streaming enables chunked reads in supported environments instead of loading entire large files. ContainerCodeExecutor now handles input/output files, while AgentEngineEnvironment improves large-file operations.
The A2A integration is also stable. The CLI can generate an agent card using “adk generate_agent_card”. Standardized inter-agent interaction helps interoperability; it does not automatically solve authentication, tenant isolation or permission propagation.
2. Why multi-run evaluation matters
MultiRunConfig, “adk eval --num_runs”, and parallelism let teams execute each evaluation case multiple times and aggregate results. The new ToolArgsMatcher can compare exact, case-insensitive, numerically tolerant or semantically matched tool arguments.
A strong demo does not reveal failure variance. Teams should report repeat-run pass rates, failure categories, cost and permitted side effects separately. LLM-backed semantic matching must not silently become the only authorization check.
3. Skill execution moves away from arbitrary shell strings
In environment mode, RunSkillScriptTool now receives validated script paths and structured arguments rather than a free-form “command” string. Google's release explicitly says the change closes a hole in which a prompt-injected model could run arbitrary shell commands.
Code, prompts or tests still providing “command” may now receive INVALID_ARGUMENTS. This narrows one dangerous entry point, but does not prove every allowed script or dependency safe.
4. Three migration-breaking changes
| Old expectation | v2.14.0 behavior | Action |
|---|---|---|
| FunctionTool enum arguments handled as raw strings | Enum member objects arrive instead | Audit string comparisons, JSON serialization and dictionary lookups |
| Arbitrary create_session config kwargs | Limited documented option set | Move state/session ID out of options; handle invalid-option errors |
| RunSkillScriptTool free-form command in environment mode | Structured arguments, validated script paths | Migrate skills, eval cases, prompts and supported script types |
These are vendor-documented behavioral changes, not measured compatibility outcomes for any particular deployment.
5. Integrations and performance
TeamsRunner connects an ADK agent to Microsoft Teams conversations. OpenAIDecisionsClassifier supports workflow/tool-gating classification questions, and MongoDbMemoryService gains vector retrieval and TTL configuration. None of these integrations automatically grants production permissions or satisfies an organization's security requirements.
Google reports 23% faster performance and 9% lower peak memory for one internal 30-node, 200-turn workflow. Without independent reproducibility, this is a vendor-specific scenario, not a universal guarantee.
6. AgentenCode readiness matrix
| Scenario | Potential benefit | Mandatory check |
|---|---|---|
| File/code execution | Stable environment APIs and chunked I/O | Filesystem/network scope, sandbox isolation, secret access |
| Multi-agent integration | Stable A2A and agent card generation | Identity, policy boundaries and approval chain |
| Quality assurance | Multi-run tests and argument matching | Case coverage, variance, safety criteria |
| Existing production ADK | New functionality | Breaking-change regression, pinned versions, rollback |
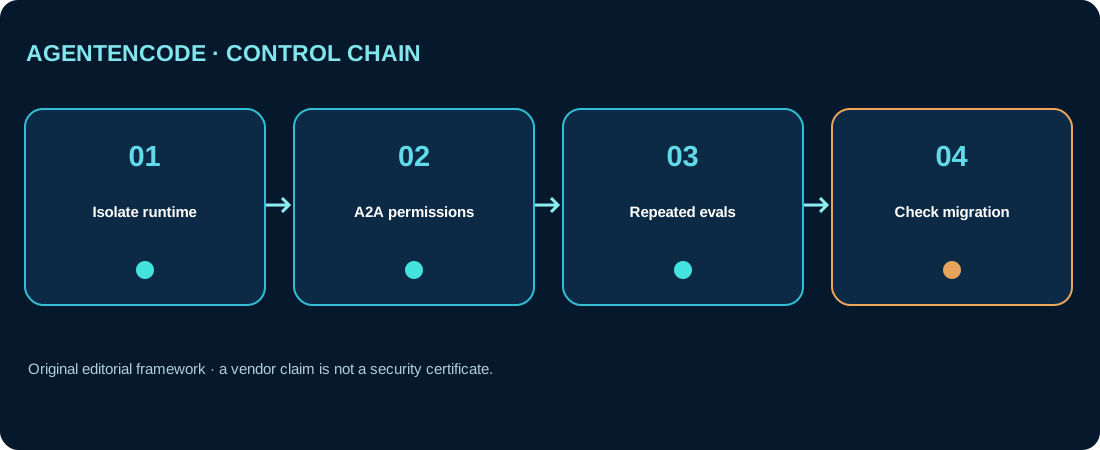
Decision: pin versions, run representative regression tests, validate environment/A2A permissions separately, and only then widen unattended execution.
7. FAQ
Does stable A2A equal secure A2A? No. API stability is not an independent end-to-end security certification.
Can skills still run any command? The updated environment mode validates paths and structured arguments and limits supported script types.
Do repeated evaluations improve the model? Not by themselves. They produce more meaningful evidence about behavior and variance.
8. Sources and methodology
- Google ADK Python v2.14.0 — official release notes
- Upstream Google ADK Python repository
- ADK A2A documentation
Method: The feature list, API changes and reported performance figures are taken from the upstream release. Decision criteria and migration matrix are independent AgentenCode editorial analysis. No hands-on security audit or external benchmark was conducted.
Media gate: Requires a distinct original cinematic master for this story, separately rendered DE/EN 1200×630 WebP covers and social JPEGs, and original language-specific decision diagrams. Publication is blocked pending media approval.