
ChatGPT and Codex will share a usage allowance in December – what agents need to know
A Help Center page updated by OpenAI on November 2, 2026 describes a coming shared allowance for ChatGPT and Codex. Starting in December, eligible usage on Plus, Pro and Business plans will draw from one token-based pool. Ordinary Instant chat is explicitly excluded. For agentic work, this is a planning change, not proof of an immediate price increase.
The provider says Plus, Pro and Business will use a common token-based allowance across ChatGPT and Codex from December. Instant chats will not draw from it. The short notice gives neither an exact rollout date nor a universal number of tokens or agent tasks per plan.
Sources and limitations
- Primary source
Dated vendor documentation with specific scope and rollout status. Read primary source.
- Not independently tested
No independent December account test, no universal quota number and no demonstrated change to every ChatGPT activity.
What the announcement actually changes
OpenAI describes the transition as part of bringing Work's agentic capabilities into the main ChatGPT experience. Eligible ChatGPT and Codex usage will be measured in tokens from a shared pool. This is not a published per-task price list or evidence that all conversations count against the same limit.
Our editorial interpretation is that complex research and software tasks become part of a more unified capacity plan. Their exact effect on an individual's usage windows remains unmeasured until the rollout reaches the account.
Which users and activities are covered
Plus, Pro and Business are expressly included. Ordinary Instant chat is expressly excluded. This distinction matters because a user asking a short everyday question should not be told that it automatically consumes the planned agentic allowance.
The page does not define an identical December mechanism for Free, Go, Enterprise, Education or separately billed API activity. It is not responsible to infer universal inclusion or guaranteed exclusion from that silence.
Tokens are not fixed job counts
A coding agent may inspect repositories, run tools and iterate through tests, while a brief chat generally has a different workload profile. OpenAI says consumption depends on model selection and task complexity. A precise conversion between a Codex run and a number of chats would therefore be invented.
Separate usage guidance discusses settings and usage windows. It can help people understand current Work and Codex allowances but does not establish a new universal December price or reset interval.
A practical usage plan for teams
AgentenCode recommends separating Instant queries, longer knowledge work and repository or cloud coding tasks. Teams should assign priority to production-critical tasks and consider whether every request needs the most intensive model and reasoning mode.
Once the new system actually arrives, measure a small set of representative tasks against the visible Settings → Usage display and repeat the measurements consistently. Claims made before that point are hypotheses, not benchmarks.
AgentenCode decision matrix
Our seven-row matrix keeps explicit vendor statements apart from operational recommendations: rollout, plan scope, eligible work, Instant exemptions, measurement, dashboard visibility and unknown prices.
The original SVG is a source-informed explanatory model of task and model choice feeding a shared allowance. It is not a screenshot of a real account.
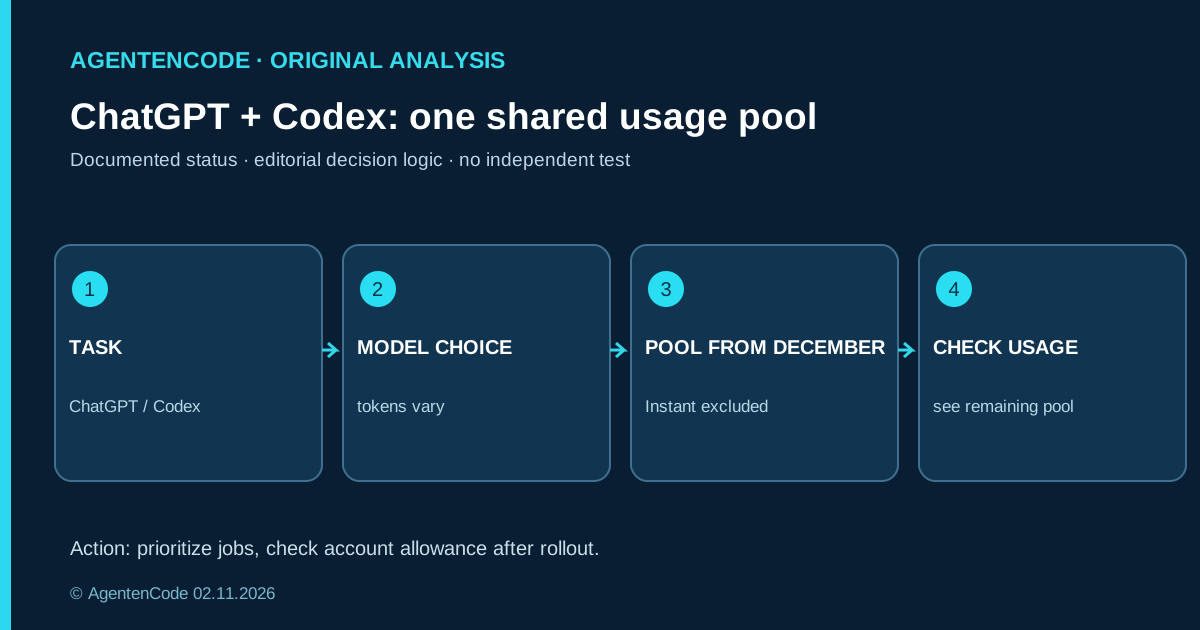
| Field | Primary-source status | Editorial decision |
|---|---|---|
| Timing | December 2026 announced | Do not claim it is live now |
| Plans | Plus, Pro and Business named | Check other plans separately |
| Pool | ChatGPT and Codex combined | Prioritize complex tasks |
| Instant | Explicitly excluded | Separate everyday chat |
| Units | Tokens; model/task dependent | Do not invent task quotas |
| Dashboard | Settings → Usage planned | Review individual usage |
| Pricing | No universal number in notice | Use current account terms |
What remains unknown
The announcement specifies December but not a calendar day. It does not publish one absolute token allowance for every named plan. Account-specific workspace policies, reset periods and credit mechanisms still need to be checked in official documentation at the time of rollout.
OpenAI expects most users not to wait for resets more often than before; this is a vendor expectation, not an independent longitudinal study. Nor does a shared allowance mean every external tool or API is included for free.
Verdict: measure before scaling
The important change is the convergence of coding and knowledge-work agents under a common usage model. Users should prioritize critical projects and watch remaining capacity and reset times after the transition.
Do not install untested budget rules using made-up quotas. Build a workload inventory and use real account data once the December model is genuinely available.
Original sources
Frequently asked questions
Is it live on November 2?
No. OpenAI says the change starts in December 2026.
Does Instant chat consume it?
The provider explicitly says ordinary Instant chat will not draw from the allowance.
How many coding tasks can I run?
No universal fixed number is given; usage varies by plan, model and task.